Claude Sonnet 5.5: same list price, different cost per task
Anthropic reports faster output and lower cost per task at the same API token prices. We separate its test results from the published tariff.
View the original post ↓Anthropic confirms the list prices and reports speed and per-task cost gains in its own tests. Benchmarks are the provider’s figures, not our independent results.
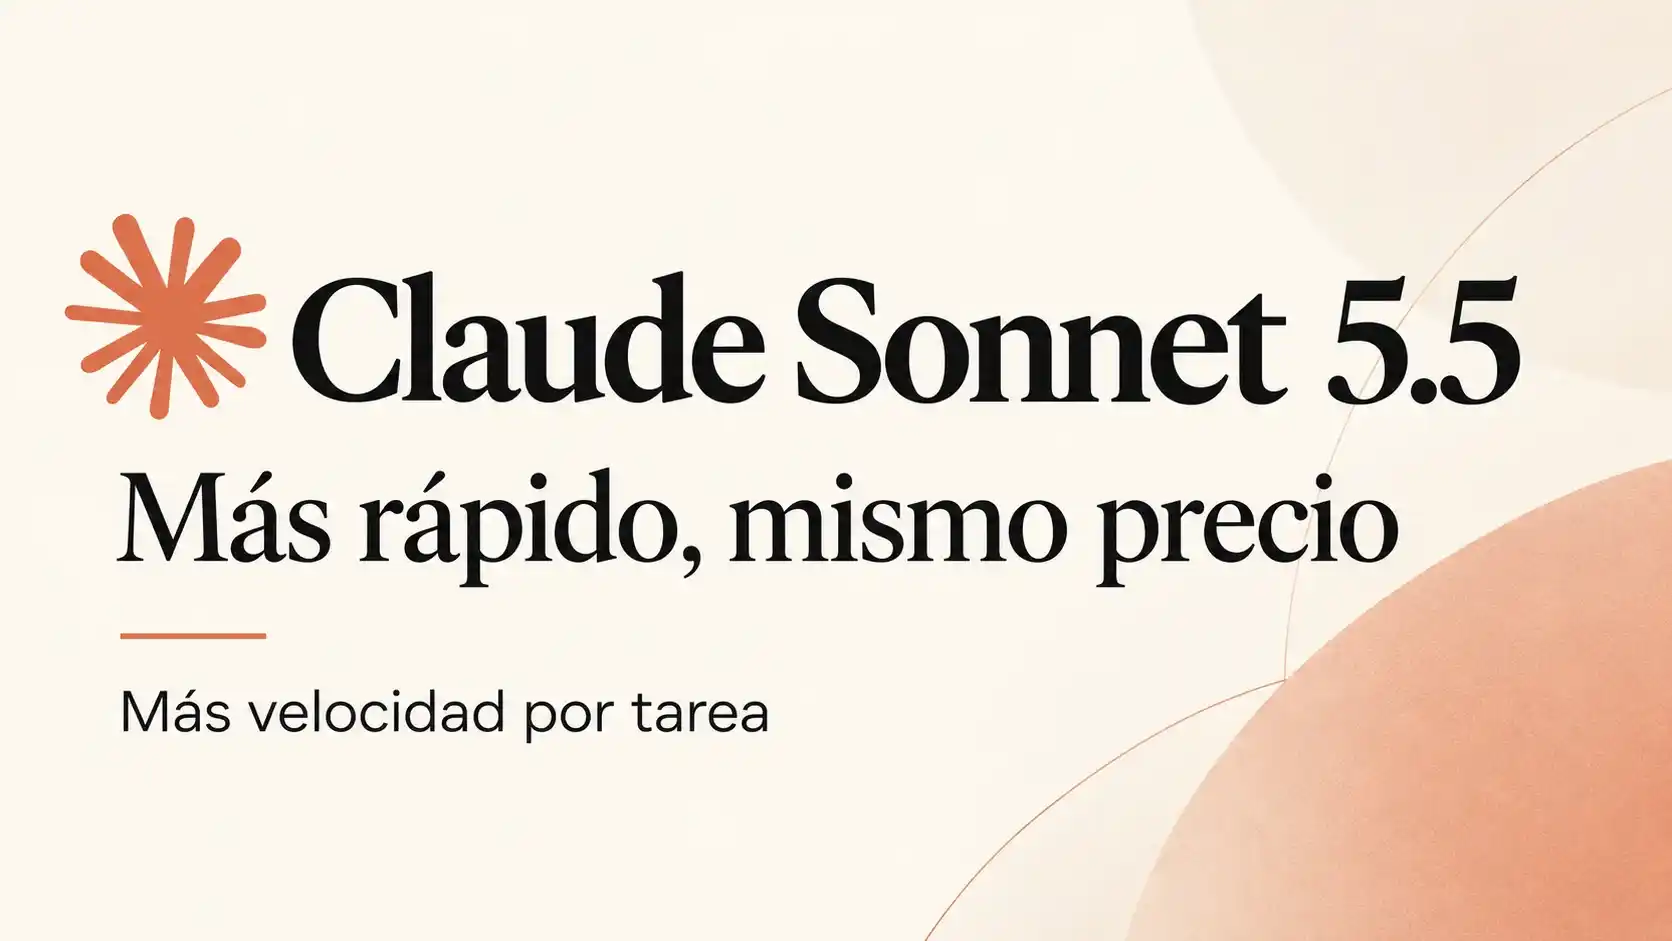
On 28 September 2026 Anthropic posted that Claude Sonnet 5.5 is now available, quoting @claudeai:
Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family. It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.
The Spanish lines in the screenshot are X’s translation of that English post. The source of record is the product page Introducing Claude Sonnet 5.5 and the API overview for model ID claude-sonnet-5-5.
This note separates the tweet, the list price, the per-task cost claim, and the benchmarks Anthropic published the same day. It is not a bake-off from this desk.
Where Sonnet 5.5 sits in the 5.5 family
Claude 5.5 is a family, not a single model.
- Opus 5.5 — launched the week before. Anthropic’s line: complex work that needs sustained judgment. List price in press coverage: $4 / $20 per million input / output tokens.
- Sonnet 5.5 — this launch. Faster, cheaper complement. Strongest, in Anthropic’s words, at well-scoped everyday tasks: bug fixes, documents, slides, spreadsheets, design polish.
- Haiku 5.5 — announced as coming in the following weeks, for high-volume and cost-sensitive work. Not available on 28 September.
The product page is explicit that a high score on a coding bench does not retire Opus:
benchmark scores capture only one facet of a model’s capabilities; in our own testing, and in that of external testers, Opus 5.5 remains clearly stronger at complex, open-ended work requiring sustained judgment.
If you only remember one sentence from the launch: Sonnet 5.5 is the default workhorse. Opus 5.5 is still the model Anthropic wants on the messy job.
What “30% faster” and “30% cheaper” actually mean
Two different statements get flattened in the tweet.
Speed. Anthropic: Sonnet 5.5 generates outputs 30%+ faster than Sonnet 5. Fastest Sonnet to date. That is generation latency, not “your whole agent run is 30% shorter.” An agent that calls tools 40 times can still spend most of the clock waiting on the tools.
Cost. The list price did not drop.
Sonnet 5 / Sonnet 5.5
- Input; Sonnet 5: $2 / million tokens; Sonnet 5.5: $2 / million tokens
- Output; Sonnet 5: $10 / million tokens; Sonnet 5.5: $10 / million tokens
- Cache reads; Sonnet 5: $0.20 / million tokens; Sonnet 5.5: $0.20 / million tokens
The 30% figure is per task, in Anthropic’s testing, because the new model “typically needs far fewer tokens to do the same work.” Reuters’ same-day report matches that reading: price per token unchanged; fewer tokens to finish the job.
API docs list the same $2 / $10, a 1M-token context window, 128K max output, knowledge cutoff June 2026, and adaptive thinking. US-only inference, when you need the run to stay in the US, is listed at 1.1× on input and output.
Read the tweet as: same sticker, smaller ticket on many jobs — if their token-use test matches yours.
The benchmark that will travel
Anthropic’s table on the launch page (their numbers):
Eval / Sonnet 5.5 / Sonnet 5 / Opus 5.5
- Eval: Terminal-Bench 4.0 (agentic coding); Sonnet 5.5: 70.6%; Sonnet 5: 10.3%; Opus 5.5: 66.4%¹
- Eval: FrontierCode 1.1 Main; Sonnet 5.5: 46.2% Max / 52.1% Xhigh; Sonnet 5: 42.4%; Opus 5.5: 54.4%
- Eval: CursorBench 4.0; Sonnet 5.5: 55.5%; Sonnet 5: 34.1%; Opus 5.5: 57.8%
- Eval: GDPval-AA v2.1; Sonnet 5.5: 1844; Sonnet 5: 1449; Opus 5.5: 1846
¹ Anthropic’s footnote on the page; methodology lives in the Sonnet 5.5 System Card.
The Terminal-Bench jump is the number every recap will repeat. Treat it as a vendor eval until you have seen the prompts, the effort setting and whether Sonnet 5 was run with the same tool budget. A 10.3 → 70.6 move on one suite is large enough that the setup matters as much as the weights.
Other first-party claims worth keeping in the same box:
- First Sonnet Anthropic says beat Pokémon Red from screenshots only.
- On GDPval-AA (44 occupations) it sits two points under Opus 5.5 and ~400 above Sonnet 5.
- At Medium effort — the default in Claude apps — Anthropic says it far exceeds Sonnet 5’s best score for less than a tenth of the cost per task.
- Early testers: more batched tool calls than Sonnet 5, fewer steps, less “search the web by reflex.”
Quoted design customers on the page (Epic, Unity, CursorBench runs, an internal 10-slide operating review) are testimonials, not a public leaderboard.
Safety: the first Sonnet with Opus-class cyber brakes
Because Anthropic rates Sonnet 5.5’s cybersecurity capability as comparable to Opus 5, this is the first Sonnet to ship with the same style of cyber safeguards and fallbacks used on the frontier models. High-risk cyber requests can fall back to Sonnet 5. Biology safeguards stay at the Sonnet 5 bar. Both, Anthropic says, target a narrow set of high-risk requests; routine software work and most life-sciences work are unaffected.
The system card (28 September 2026) adds the RSP framing: Sonnet 5.5 is broadly less capable than Opus 5.5 across those domains and does not cross new Responsible Scaling Policy thresholds. It is described as the most robust Sonnet-class model yet against prompt injection in coding and browser-use evals. Refusal on malicious computer-use tasks is listed as matching Opus 5.5 — and as a regression versus some earlier models.
That last clause is the one to keep if you run agents against a browser: more capable at cyber than Sonnet 5, wrapped in heavier brakes, not “safe because it is a Sonnet.”
Where you can actually call it today
Anthropic:
- Claude.ai on web, iOS and Android.
- Claude API as
claude-sonnet-5-5. - Amazon Bedrock / Claude Platform on AWS (Global CRIS profile called out in AWS’s own post).
- Google Cloud and Microsoft Foundry listed on the Sonnet product page.
API docs flag five breaking changes for code already on Sonnet 5, plus a response-shape change (text between tool calls comes back in thinking blocks). If you swap the model ID and a tool loop breaks, read the migration guide before blaming the weights.
Reuters notes Anthropic is expanding the 5.5 lineup while it builds toward an IPO. That is business context, not a product spec.
What I would do with it this week
- Keep Opus 5.5 on architecture, ambiguous specs and anything you would not want a mid-tier model to “finish.”
- Point Sonnet 5.5 at the jobs Anthropic named: scoped bugs, slides from a template, spreadsheet cleanup, a first pass on a well-described feature.
- Measure tokens per closed ticket, not only tokens per minute. The whole cost story is token use, not the $2 / $10 row.
- If you have Sonnet 5 in production, read the five API breaking changes before you flip the ID.
Frequently asked questions
Did the API price fall? No. $2 in / $10 out, same as Sonnet 5. The “up to 30% less” line is cost per task in Anthropic’s tests.
Is Sonnet 5.5 better than Opus 5.5? On Terminal-Bench 4.0 Anthropic reports a higher score than Opus 5.5 at the setting they published. On open-ended work they still call Opus stronger. Use the job, not the leaderboard screenshot.
Is Haiku 5.5 out? Not on launch day. “Coming weeks.”
Does this replace the Opus 5.5 note already on the main meuveryone blog? No. Different site, different job. This Observatorio piece is the Sonnet 5.5 launch. The older Opus Arena article on meuveryone.com is a separate text.
Takeaway
Sonnet 5.5 is Anthropic putting the mid-tier back in front of everyday work: same list price, a claimed smaller token bill, a very large vendor jump on one coding bench, and cyber brakes that used to sit only on the frontier models. Opus stays the model they will not let a leaderboard retire.